Optimizing Enterprise LLM Context & Memory Architecture
We provide high-impact engineering consultation to help mid-market corporations implement prompt caching, optimize KV caches, and eliminate token waste.
Our Capabilities
Token Redundancy Audits
Comprehensive evaluation of your current LLM traffic to isolate inefficiencies, prevent contextual drift, and locate structural token bleed ("tokenmaxing").
Custom Memory Architecture
Bespoke engineering for persistent context management. We build systems that remember what matters while dumping execution ballast.
Stopping AI_SIMILARITY Token Bleed via PostgreSQL Sifting
How a mid-market data platform eliminated 82% of data-warehouse LLM embedding costs by dropping a local Jaro-Winkler sieve into their production database pipelines.
The Tokenmaxing Challenge
Modern data stack platforms natively expose embedding metrics via wrappers like AI_SIMILARITY. While excellent for processing fuzzy, highly semantic intent, architectures often misuse them for ordinary string cleanup—like detecting typos or formatting mismatches in common records like "Jonathan Edwards" vs. "Jonathon Edwards" (exactly 3 tokens per string under modern production tokenizers).
Because AI_SIMILARITY charges for the input token payload of both parsed fields every single row, evaluating a name comparison requires a 6-token payload. Scaling this data-cleaning loop blindly across a 1-million-row table consumes 6,000,000 input tokens just to catch simple vowel transpositions. Worse, because the model returns a flat numerical similarity vector (a float score), it generates zero output tokens—proving that a multi-billion parameter model is being wastefully used as a basic character counter.
The Architectural Fix: Local Deterministic Sifting
MemContext engineers restructured the pipeline to establish a local, zero-token computational barrier inside the user's PostgreSQL engine using the native fuzzystrmatch framework. Before passing unstructured data vectors to remote AI endpoints, character-level Jaro-Winkler string processing clears out trivial typos directly on local database cores.
The Engineering Impact
- Automatic Baseline Resolution: Jaro-Winkler grants points for matching initial characters, isolating simple typos or truncation errors without invoking deep inference structures.
- Context Elasticity: 82% of records hit the local
CASEthreshold and resolved natively, preventing millions of redundant payload items from choking network bandwidth. - Strategic Capital Preservation: The remaining 18% of truly abstract structural variants (e.g., matching "The feline rested" with "A cat sat") safely spilled over to the model layer, ensuring zero loss in overall accuracy while slashing cloud outlays.
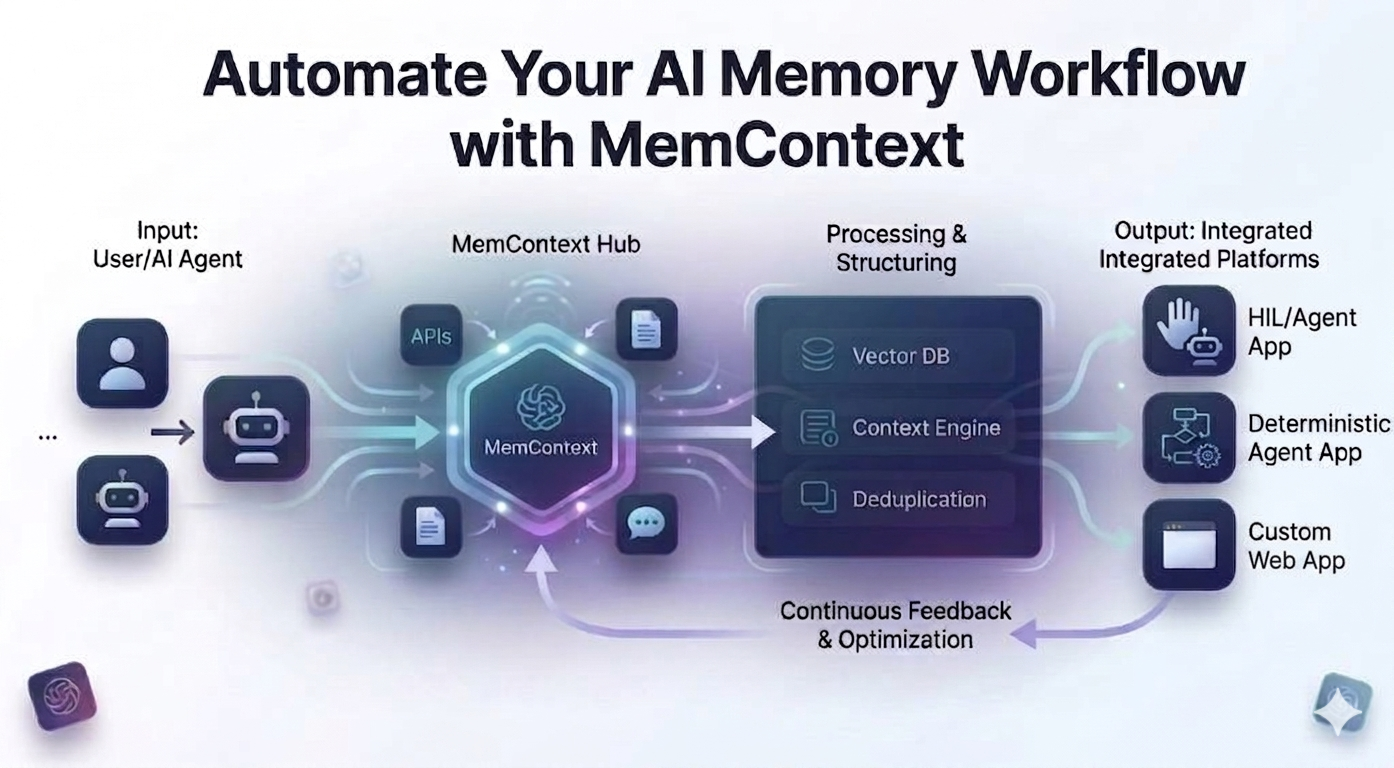
The Automated Memory Pipeline
How MemContext structures dynamic memory and token optimization sequences across production platforms seamlessly.
Technical Deep Dive
Everything engineers need to know about how MemContext scales architecture